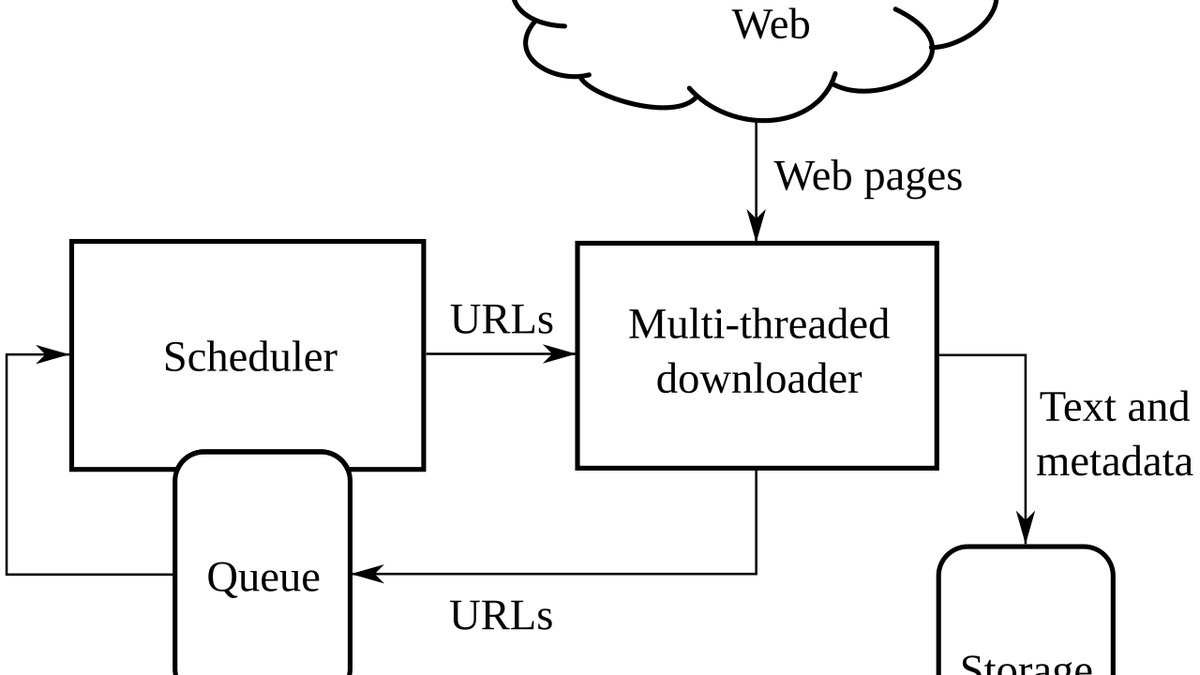
Meta has removed a clause from its terms that critics argued could enable large‑scale web scraping for AI training. The company says the change does not alter how it crawls the web.
Core Facts
- Clause removed from updated terms.
- Spokesperson confirms no change in crawling approach.
- Scraping concerns tied to AI model training.
- Meta maintains existing data‑collection policies.
- Industry watchers note the move amid growing scrutiny.
Background on Meta’s Data‑Harvesting History
Meta has long faced backlash over its data‑collection practices, especially after the 2023 lawsuit alleging unauthorized use of user content for training its AI models. Earlier this year, the company updated its privacy policy to clarify its data‑usage stance, sparking debate among privacy advocates and AI researchers. The removal of the contentious language follows a wave of regulatory pressure in the U.S. and EU to tighten rules on automated data harvesting.
Future Impact on AI Training and Regulation
While Meta claims its crawling remains unchanged, the tweak may placate some regulators and reassure users concerned about data misuse. However, AI developers still rely on publicly available web data, and the clarification could influence how companies negotiate data‑access agreements. The move also signals a broader industry trend toward clearer terms as governments push for stricter oversight of AI training data.